Incremental Load: Deleted and Back-Dated Records
Incremental loads are fast but silently miss deleted and back-dated records. How watermarks, overlap and full reloads help, and what Floemdata does today.
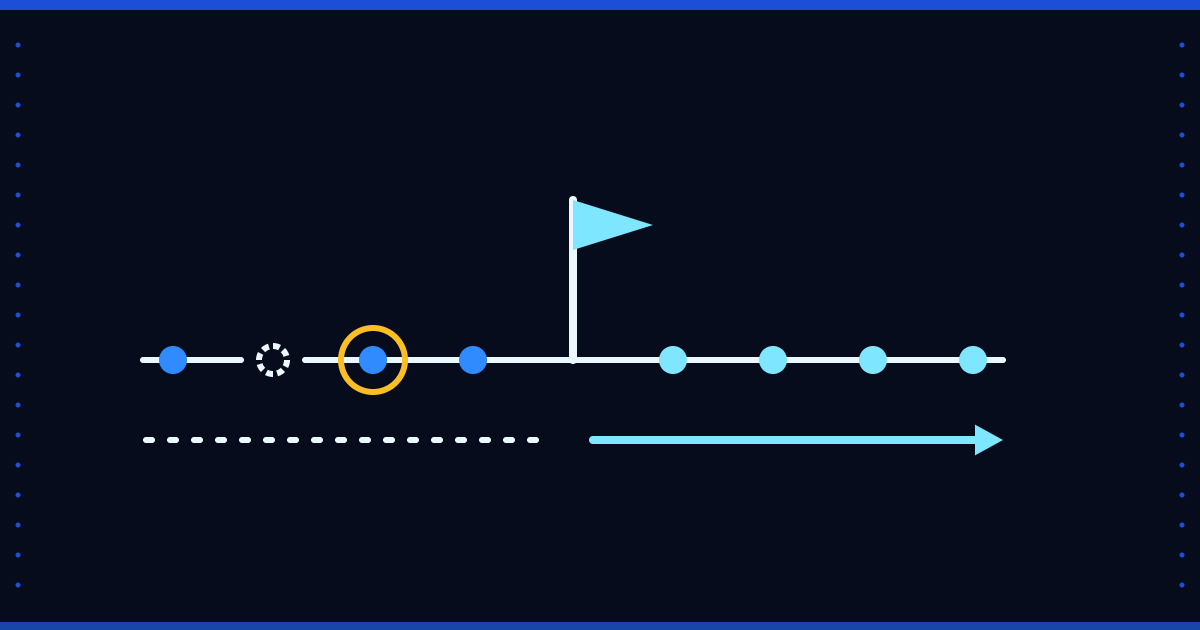
Pulling every invoice from scratch each night gets slower over time, even in a small company. The usual fix is to fetch only what changed since the last run. That method silently misses two kinds of records: those deleted in the source and those whose date was set back. The report comes out wrong and no error message appears.
How an incremental load works
The warehouse remembers how far it has read in a watermark: a change date or an increasing number. The next run asks only for what lies beyond that point. The watermark must advance only after the write succeeded, otherwise a half-finished run skips records for good.
Trap 1: the date has no time of day
If the change date holds only the day, a record edited later that same day may stay invisible, because the watermark has already reached that day. The remedy is to read slightly behind the watermark (overlap) and make the load repeatable. If the same record arrives twice, the result must not change, so the write has to be an upsert by key, not an insert.
Trap 2: back-dated entries
In accounting and stock movements the document date need not be today; a movement can be entered three days later with an old date. A watermark that follows the document date never sees it. A sturdier key is a sequence number that the source assigns automatically at the moment of posting.
Trap 3: deleted records
A deleted row cannot appear in a change-date query, because there is no row left to update. Known ways to catch deletions in an incremental setup:
- Flag instead of delete: if the source marks records cancelled rather than deleting them, carry the flag. Do not filter cancellations out.
- Periodic full reload: for small tables (customers, items, warehouses) pull everything and compare; a record missing from the latest pull was deleted.
- Key comparison: for large tables pull only the keys and compare them with the warehouse, which is far cheaper than all rows.
Where Floemdata stands
According to the project documents and code, Floemdata uses four extraction patterns. For document headers, the incremental pattern reads the header change date a set number of days behind the watermark (overlap). The project notes record that SAP's change date carries no time of day, and the write is an upsert by key. Cancelled documents are not filtered; the cancellation is carried into Bronze. For tables that can be posted back-dated, such as stock movements, the progress key is the movement sequence number, not a date. The watermark advances after the Bronze write has been confirmed.
For deleted records the only route the code names is the full reload: small master-data tables are pulled in full and Silver compares them. We did not find a mechanism that catches a physical deletion in the large document tables, so do not assume a document deleted in SAP will disappear from the warehouse. These behaviours were tested against mock SAP data; the deletion scenario was not verified on a real customer system.
To begin, delete one record in your own source and check what the warehouse shows after the next load. If the answer surprises you, that is where the problem and the fix start. Questions are welcome at info@floemdata.com or via Floemdata.